Work Wharton Research Data Services
10 terabytes of news, ingested 10x faster
A 10 TB news corpus with 25 GB landing every day. The naive importer was never going to hold.
- Client
- Wharton Research Data Services
- Role
- Data Engineer
- Period
- 2019 to 2023
- Focus
- Data Engineering
- 10 TB total corpus
- 25 GB ingested daily
- 10x faster than the naive import
I owned data engineering for a 10 terabyte news dataset taking on 25 gigabytes a day. Row-by-row inserts were not going to survive that, so the import had to be rebuilt around how Postgres actually wants to be fed.
What made it 10x
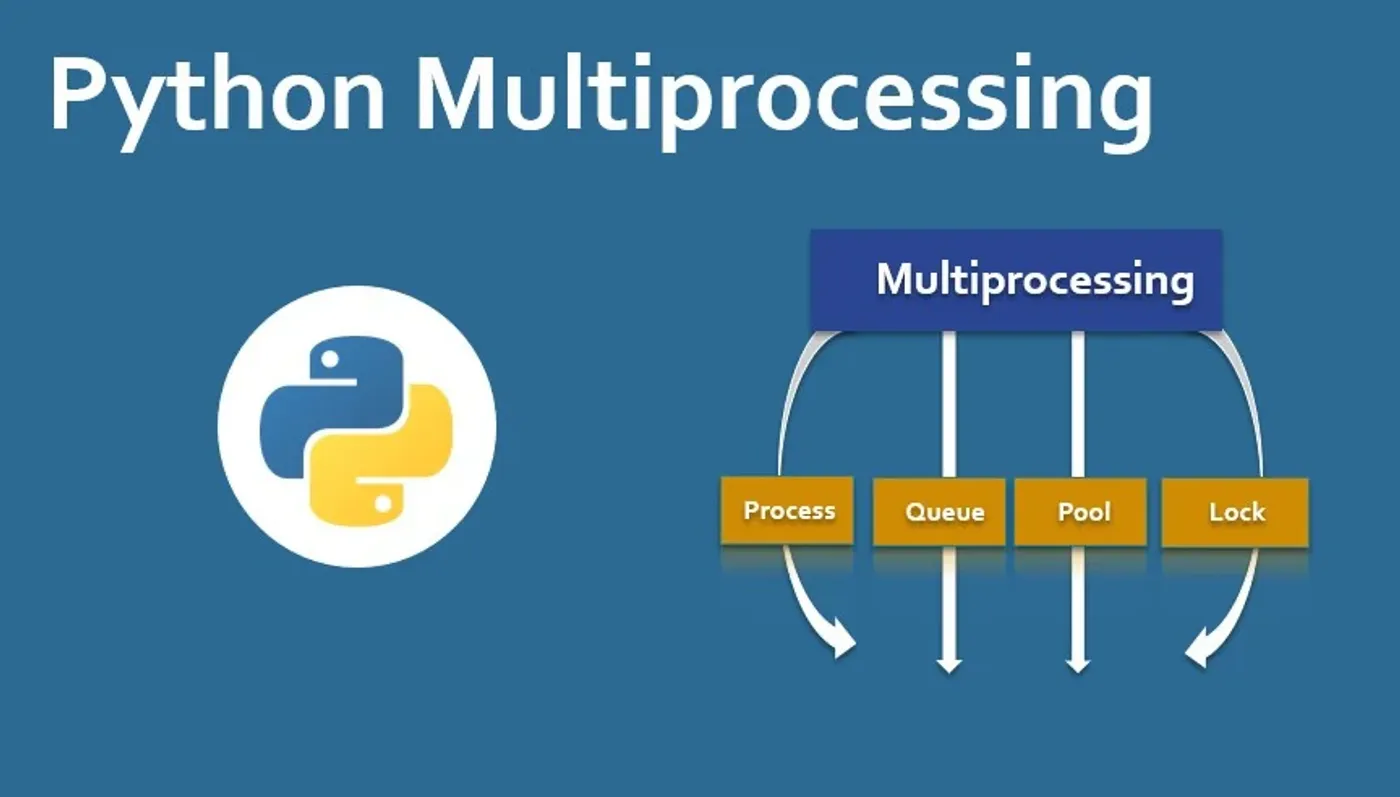
Python multiprocessing in front of Postgres COPY FROM CSV, instead of ordinary
inserts. I used JupyterHub to run the speed experiments before committing to an
approach, so the design was chosen on measurements rather than instinct.
I designed both the Postgres schema and the Elasticsearch search schema. The Elasticsearch side was shaped deliberately to keep AWS costs down while leaving the research and development team room to work, since an index designed purely for query convenience gets expensive quickly at this size.
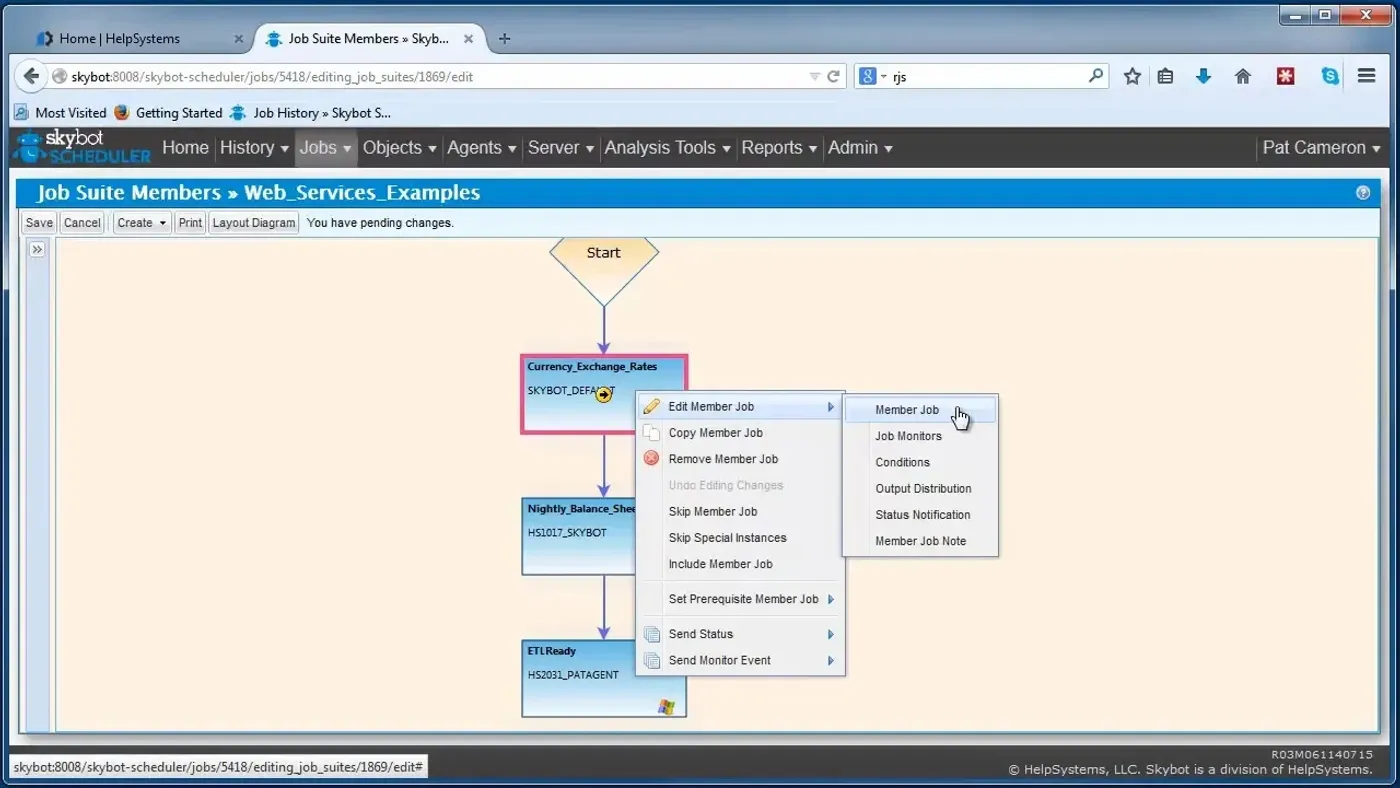
I worked with the platform team to confirm the database servers could actually absorb the import at that rate, and used Automate Schedule to run and monitor the ETL jobs.
Screens